A focused 2-hour course for finance professionals: decide which data may go into which AI tool, then prepare masked or summarised inputs that keep restricted details out.
What you will be able to do
- Know what's sensitive in your files: Sort the columns and files in a finance dataset into customer identifiers, bank and credential details, unreleased results, internal data and figures that are already public. This includes what hides in file names, sheet tabs, comments, hidden columns and free-text fields.
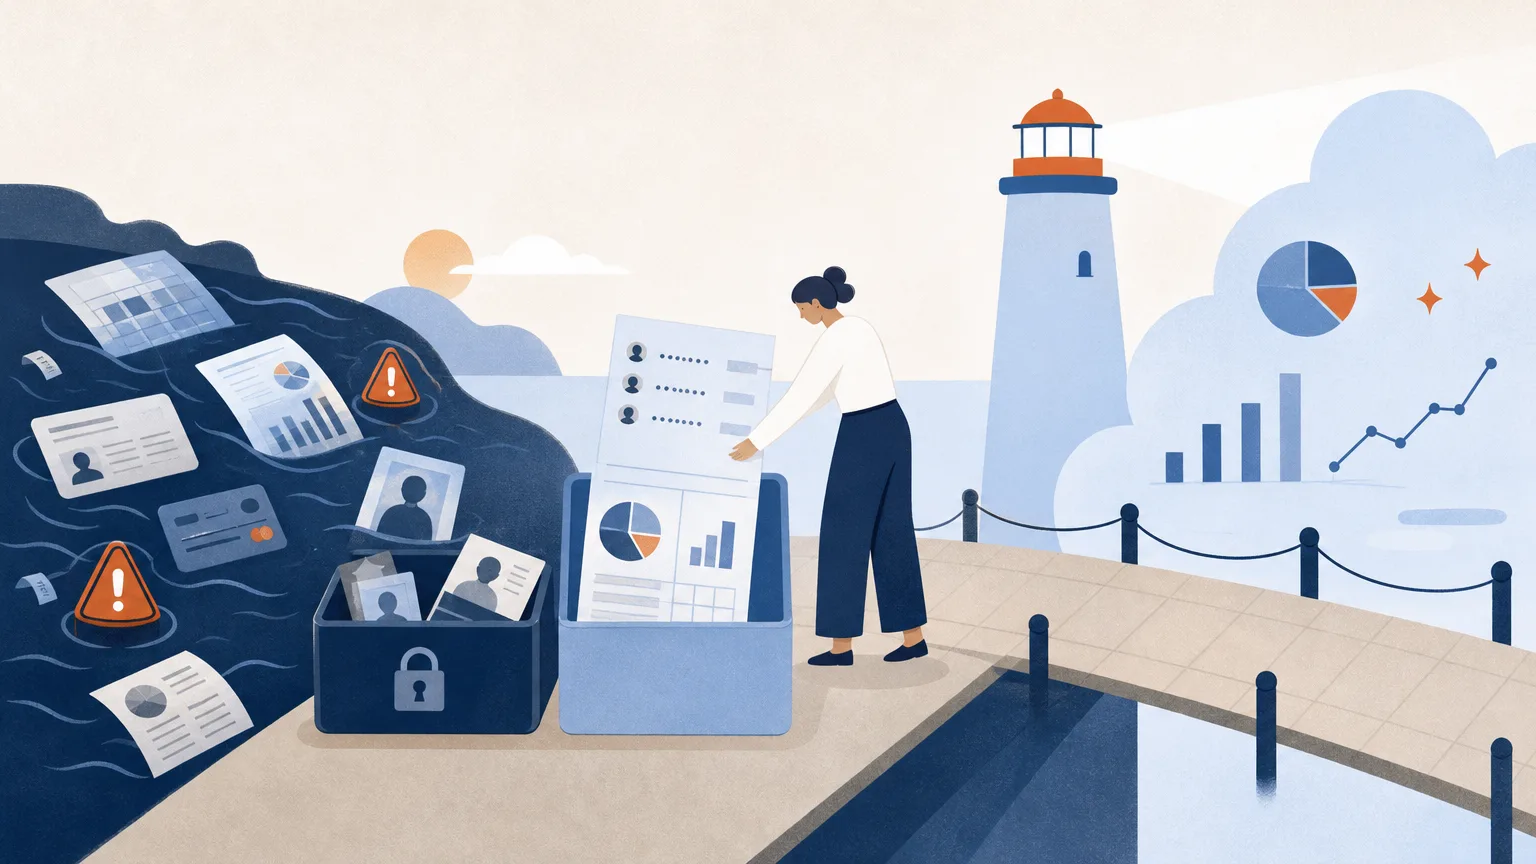
- Mask identifiers and credentials: Make a masked working copy of a file, such as a receivables ledger, where customer IDs and bank details become consistent tokens and credential fields are removed. Your totals and analysis still work.
- Summarise instead of sharing rows: Turn restricted records into totals, counts, ranges or bucketed aggregates that answer your question. Spot when an aggregate is so small or specific that it still points to one customer.
- Match data to approved tools: Build a simple table matching each data class to the AI tools your organisation approves for it. Pick the right tool based on a file's most sensitive content, and stop when no approved tool covers it.
- Check before you share: Run a pre-submission check on what you paste in and on what comes back. Look for leftover identifiers, bank details, unreleased figures, or a changed period, currency or unit.
- Keep your analysis traceable: Add a short context header to every prepared input stating the period, currency, units, source and calculation method, so anyone can follow how a figure was produced.
Taught at learn.m-a-s-t-e-r.ai: lessons that adapt to your level, an AI tutor you can ask anything, quizzes and flashcards, and a certificate when you finish.